Blender In Depth
Lets deep dive into blender’s DNA. What composes blender? What can be modified? and what is the blender way?
Blender is a complex and big project managed by blender studios, as the official orchestrator, many collaborators and volunteers. This combination makes blender a fast evolving application that needs lots of documentation. For this reason, there are many sources we can use to try answer What is blender?
What is Blender?
In its essence, blender is just a collection of Python, C++, C, GLSL and CMake scripts. But nothing explains better what this code does than the official page itself:
Blender is the free and open source 3D creation suite. It supports the entirety of the 3D pipeline: modeling, rigging, animation, simulation, rendering, compositing and motion tracking, even video editing.
Development of Blender happens at projects.blender.org and is funded entirely by donations from entrepreneurs, companies, and users.
And because the good resources are the ones that exist, we will rely in blender’s already official documentation to dive into its skeleton.
- https://developer.blender.org/docs/handbook/contributing/using_git/#github-mirror
- https://docs.blender.org/manual/en/latest/
- https://docs.blender.org/api/current/
- https://developer.blender.org/docs/
- https://studio.blender.org/welcome/
- https://www.youtube.com/@BlenderOfficial
- https://www.youtube.com/@BlenderStudio
- https://extensions.blender.org/
- https://developer.blender.org/docs/handbook/new_developers/navigate_code/
- https://www.youtube.com/live/tCdx7gzp0Ac?si=PskMa_x3hDusAtD3
This is … in fact … overwelming.
Introduction
Lets not get too ahead of ourselves. Blender is composed of modules and the combination of all them creates the project we know and love. For that reason we will explore each of them on depth in the future but for now we want to understand the machinery behind the nature of Blender.
Blender’s code
Blender source code can be found in two official places, their web page and in a github mirror:
- https://github.com/blender/blender
- https://projects.blender.org/blender/blender
At this point in time (26/09/2026) we see the following structure:
blender
├── assets
├── AUTHORS
├── build_files
├── .clang-format
├── .clang-tidy
├── CMakeLists.txt
├── COPYING
├── doc
├── .editorconfig
├── extern
├── .git
├── .gitattributes
├── .git-blame-ignore-revs
├── .gitea
├── .github
├── .gitignore
├── .gitmodules
├── GNUmakefile
├── intern
├── lib
├── locale
├── make.bat
├── pyproject.toml
├── README.md
├── release
├── scripts
├── source
├── tests
├── tools
└── .well-known
And it is composed mainly of c++. That does not strictly mean that development implies knowing c++ but it will be handy ;)
| Language | % |
|---|---|
| C++ | 80.8% |
| Python | 15% |
| C | 1.5% |
| CMake | 1.2% |
| GLSL | 0.8% |
| Objective-C++ | 0.7% |
To prevent overcomplicating things too early, i will not expose the underlying code yet. First I want to focus on the idea blender and many other softwares use to split responsibility on code.
Blender code is in charge of two things: Exposing the data structure and Exposing the functionality. This becomes clear when we split the Graphical user interface and the operators under those buttons against the .blend file that contains plain data like the vertex information. This two things are “independent”.
I find interesting to explore the data we are working on before studying how we operate on it. Inside blender code we find a few structures that we use virtually always: Mesh and Object. Remember that this is an example, the real structures are more complex.
Each object can point towards a mesh ID, which means a single mesh can be reused for many object. This is known as instance and it is used during rendering to lower memory usage and speed up rasterization.
Instances are widely explored in the literature so I will assume we already know them, otherwise I invite you to explore by yourselves how they work.
In this minimal example, Mesh structure takes 448 bytes independently of the mesh number of vertices.
Mesh                                      size    offset
├── ID id                                  408       0
├── int verts_num                            4     408
├── int edges_num                            4     412
├── int faces_num                            4     416
├── int corners_num                          4     420
└── AttributeStorage attributes             24     424
                                          ─────
                                           448 bytes
To do so we follow the same strategy as Instances. We store the real geometry (verts, edges, faces) on a different structure. Mesh points to them through this AttributeStorage structure. Therefore, even if the number of verts changes at runtime, we dont need to update the Mesh structure itself unless we want to update the verts_num for example.
We will explore more about this in the future but for now just keep in mind that this conceptual elements called “object” and “mesh” exist as data in some kind of format blender can read.
A .blend file will work as the database. This becomes clear when we try to link or append structures inside a new blend file, you just have to notice how the search tree shows each element as a folder with multiple files inside.
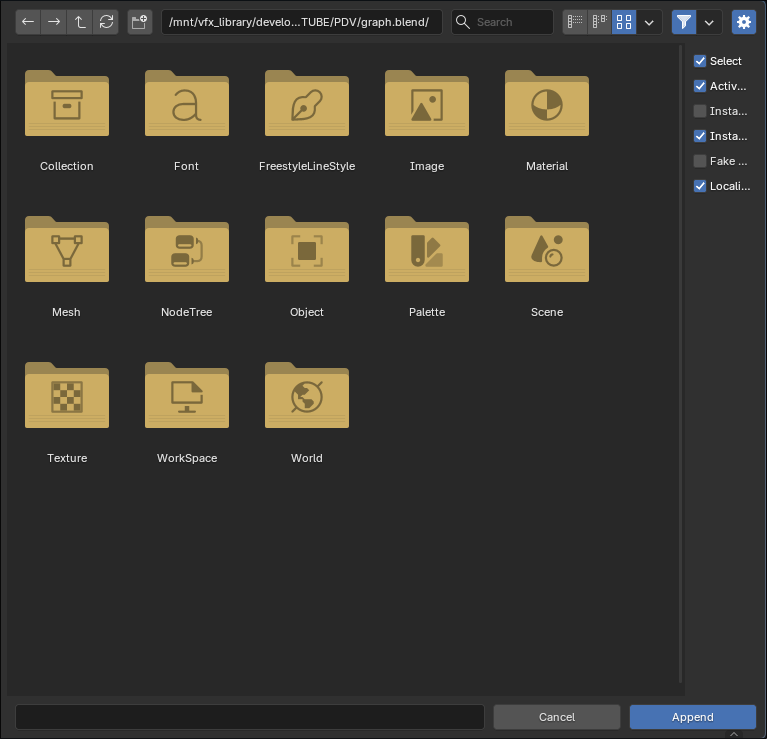
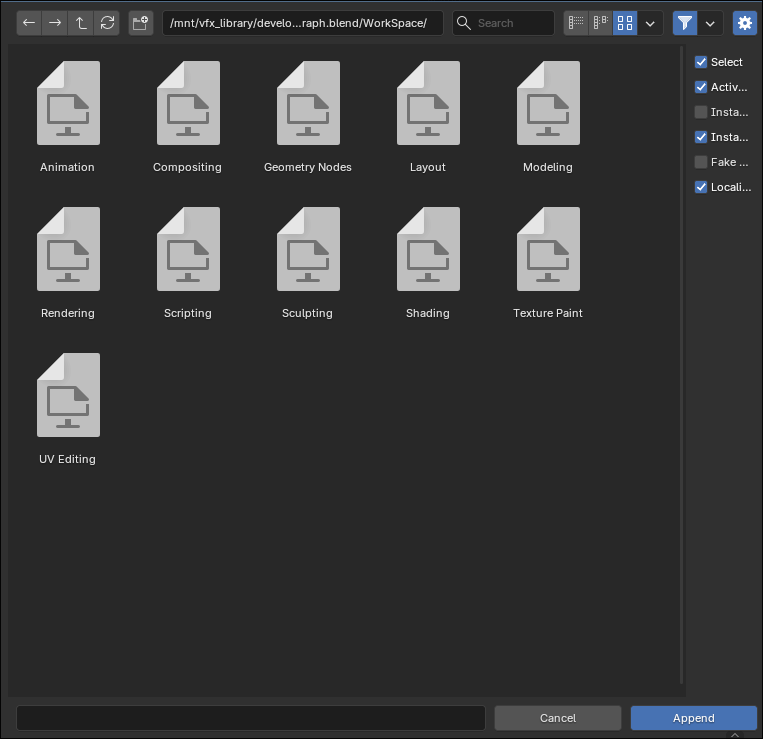
But even more convenient is blender’s built in file explorer where we can see all the information being stored in the current file.
In image 2, after opening blenders “Current File” tree, we observe two meshes called spring and Suzane as well as three independent objects that reference both meshes. Monky1 and Monky2 do in fact share the same Mesh, meaning that any modification on Suzanne mesh will be visible by both objects inmediatly.
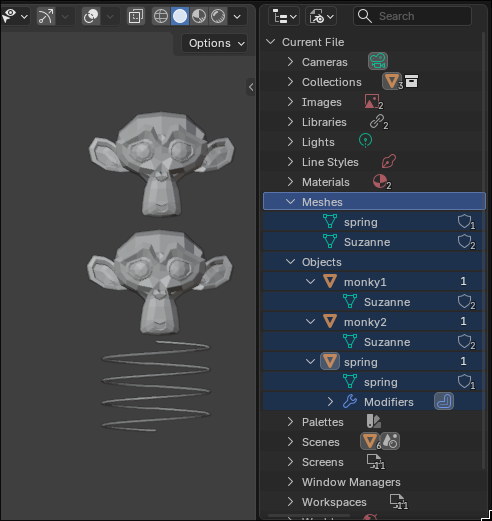
With this introduction I want that, from now on, we think of blender files as something similar to a file tree instead of a complex window system with many labels. The separation is simple, the .blend file will only contain the database while blender’s executable program will be in charge of presenting the information.
  file.blend
  ├── scenes/
  │   └── Scene
  ├── collections/
  │   └── Props
  ├── objects/
  │   ├── Spring
  │   ├── Monkey1
  │   └── Monkey2
  ├── meshes/
  │   ├── Spring
  │   └── Suzanne
  ├── materials/
  │   ├── Brass
  │   └── Skin
  ├── lights/
  │   ├── Key
  │   └── Fill
  ├── cameras/
  │   └── Camera
  ├── images/
  │   └── skin_diffuse.png
  └── node_groups/
      └── Push
Blender Binary File
At https://docs.blender.org/manual/en/5.2/files/blend/open_save.html we are explained that .blend format is by default a Zstandard compressed file. Interestingly, a non compressed .blend file will expose human readable hexadecimal data. Lets take a look.
For this purpose I will use an uncompressed blend file and neovim with hexadecimal reading option :%!xxd -g 1. The first thing that calls my attention is the blender versions stored on the header:
Position   Bytes in hexadecimal                             ASCII code
____________________________________________________________________________
00000000:  42 4c 45 4e 44 45 52 31 37 2d 30 31 76 30 35 30  BLENDER17-01v050
00000010:  32 52 45 4e 44 00 00 00 00 10 00 00 00 00 00 00  2REND...........
00000020:  00 08 01 00 00 00 00 00 00 01 00 00 00 00 00 00  ................
00000030:  00 01 00 00 00 c3 ba 00 00 00 53 63 65 6e 65 00  ..........Scene.
The values on the left column are 00000000, 00000010, 00000020, …, but don’t worry, they are just visual. In short it is just the number of the line but instead of having the common [1,2,3,4,5] we are provided the offset of bytes per line. The first line has an offset of zero bytes while the second line starts after 16 bytes from the beginning of the file.
Before proceeding any further, please become familiar with what a bit, byte and hexadecimal are. You can read the following annotations to develop a bit of intuition.
Memory is made up of bits. A bit is simply a value that can have one of two states: 0 or 1.
In fact, we can combine multiple bits to represent larger numbers. Any decimal value can therefore become a sequence of binary values:
0  =   0       8 = 1000
1  =   1       9 = 1001
2  =  10      10 = 1010
3  =  11      11 = 1011
4  = 100      12 = 1100
5  = 101      13 = 1101
6  = 110      14 = 1110
7  = 111      15 = 1111
I decided to represent the binary form of the sixteen first decimal values because they offer an interesting property for representation. It turns out that memory is divided in chunks of eight bits that we call a Byte. If we tried to represent a file grouping each byte we would simply see groups of eight binary values which is not really useful for humans. Instead, programmers came up with an idea to represent such values as two single characters.
The system consists on dividing a byte in two segments of four bits and replacing the four bits by a single hexadecimal value.
| Binary has 2 digits:   0 1
| Decimal has 10 digits: 0 1 2 3 4 5 6 7 8 9
| Hex has 16 digits:     0 1 2 3 4 5 6 7 8 9 A B C D E F
By convention, since our system only has 10 different symbols, we borrowed letters from the alphabet to represent the rest. This is a convention therefore we could use any set of symbols to represent hexadecimal, it is just that this was convenient because most languages already recognize those symbols.
| Decimal: 0 1 2 ... 9 10 11 12 13 14 15 16 17 18 ... 24 25 26 27 28
| Hex:     0 1 2 ... 9  A  B  C  D  E  F 10 11 12 ... 18 19 1A 1B 1C
What matters here is what each position means in the numerical system. In the decimal system, value 18 means we have “1” tens and “8” units while in hexadecimal it is translated as value 12 which means “1” sixteen and “2” units. Both are “the same number of oranges” but they have a different symbols to be represented. Can you transform 8B oranges to decimal system? Answer: we have eight sixteens and B units -> 8*16+11 = 139 oranges.
| Decimal 18 = 1 sixteens + 2 = hex 12
| Decimal 139 = 8 sixteens + B = hex 8B
Lets go back to the first line which is known as the header of .blend. When we open a file, we are usually presented with sixteen bytes for each line, or in other words, 32 hexadecimal values. The file has no lines, It is a single long line but for a screen this would become a headache.
I know for a fact that the header of the blender file is 17 bytes long so i will show them below.
00000000: 42 4c 45 4e 44 45 52 31 37 2d 30 31 76 30 35 30
00000010: 32
Now we can see more information than before, grouping data helps us recognize patterns. The problem is that unless we know what we are looking for, it still takes a long time to process the information on our heads. The solution to this is called ASCII, a table containing a set of human readable symbols:
    0 1 2 3 4 5 6 7 8 9 A B C D E F
2x    ! " # $ % & ' ( ) * + , - . /
3x  0 1 2 3 4 5 6 7 8 9 : ; < = > ?
4x  @ A B C D E F G H I J K L M N O
5x  P Q R S T U V W X Y Z [ \ ] ^ _
6x  ` a b c d e f g h i j k l m n o
7x  p q r s t u v w x y z { | } ~
If you notice, we have six rows and sixteen columns. This was designed to be encoded in a single byte, in other words two hexadecimal values.
We know (by design) that blender’s first 17 bytes are in fact ASCII characters therefore we can decode and read them.
Remember that this is the first line of the file:
42 4c 45 4e 44 45 52 31 37 2d 30 31 76 30 35 30 32
Byte (binary)  Hex   ASCII
0100 0010   -> 4 2    B
0100 1100   -> 4 C    L
0100 0101   -> 4 5    E
0100 1110   -> 4 E    N
0100 0100   -> 4 4    D
0100 0101   -> 4 5    E
0101 0010   -> 5 2    R
0011 0001   -> 3 1    1
0011 0111   -> 3 7    7
0010 1101   -> 2 D    -
0011 0000   -> 3 0    0
0011 0001   -> 3 1    1
0111 0110   -> 7 6    v
0011 0000   -> 3 0    0
0011 0101   -> 3 5    5
0011 0000   -> 3 0    0
0011 0000   -> 3 2    2
But of course we don’t have to do this manually each time. Instead, nvim or other file readers usually offer an automatic translation “if” the hexadecimal can be translated. This means that sometimes we will get random generated text because it matches an ASCII entry. Please note that for the sake of saving space, I will remove the space between pairs of bytes.
00000160: c280 0000 0048 0000 0027 2727 c3bf 2a2a  .....H...'''..**
00000170: 2ac3 bf2a 2a2a c3bf 1f1f 1fc3 bf30 3030  *..***.......000
00000180: c3bf 2929 29c3 bf2b 2b2b c3bf 2424 24c3  ..)))..+++..$$$.
00000190: bf2a 2a2a c3bf 2020 20c3 bf2c 2c2c c3bf  .***..   ..,,,..
000001a0: 2a2a 2ac3 bf27 2727 c3bf 2020 20c3 bf18  ***..'''..   ...
Going back again to the first lines of the file, we have 17 bytes that contain the headers information. Because of the reading program we use, nvim, we split the header in groups of 16 bytes but notice that the integer “2” on the second line belongs to the header:
00000000: 424c 454e 4445 5231 372d 3031 7630 3530  BLENDER17-01v050
00000010: 3252 454e 4400 0000 0010 0000 0000 0000  2REND...........
00000020: 0008 0100 0000 0000 0001 0000 0000 0000  ................
00000030: 0001 0000 00c3 ba00 0000 5363 656e 6500  ..........Scene.
The first 7 bytes 424c 454e 4445 52 are translated as BLENDER. If we ask blender to read a file and it does not start with those exact characters, we notify the user this file is not readable by blender.
The next two bytes (16 bits) are meant for storing the byte size of the header. In those 16 bits we could represent any value between 0 and 65535. If we had bits 00000000 00010001, grouped them in bytes and represent them in hexadecimal, we would get 0011 successfully storing the size of the header.
Funny enough, this is incorrect not because of the math but because blender’s developers decided to store the values in ASCII instead of 16 bit integers. The real file has the hexadecimal values 31 37 that can be converted to ASCII as 17. We will take this as a future lesson, unless we know what the underlying binary represents, we cant translate it properly. I know what all this bytes are meant to represent because I looked at the source code.
The next byte is just a separator used in older files so the parser understands that we now have to interpret the rest of bits in a different way, for now we can ignore it.
The next two bytes also in hexadecimal representing a value are translated to 01. Blender’s recent updates have modified the header shape because it was no longer capable of representing certain data. For example, they had to extend the bytes representing “version” because they expect a blender 10.0 in the future that 3 bytes where not able to represent in ASCII. In this change they also introduced the file’s version that in future case when the data arrangement inside blender changes, they just have to update the value in the header to specify the parser which version it has to use.
The v byte in the header is for the endian type and the following four bytes are for the blender version the file was saved with.
| Bytes | Text | Meaning |
|---|---|---|
| 7 | BLENDER |
Magic word identifying a .blend file |
| 2 | 17 |
Size of this header in bytes (17) |
| 1 | - |
Separator (in older files this spot meant 64-bit pointers) |
| 2 | 01 |
Version of the file format itself |
| 1 | v |
Byte order: lowercase v = little-endian, uppercase V = big-endian |
| 4 | 0502 |
Blender version: 5.2 |
Right after the header, at byte 0x11 (1*16 + 1), we find the main contents of the document. There is one issue, each group of data can have arbitrary lengths and we have no way of knowing when a chunk starts or ends. To solve that issue blender has declared the following structure at blender/source/blender/blenloader_core/BLO_core_bhead.hh. Now all headers will have this shape:
struct LargeBHead8 {
  int code;
  int SDNAnr;
  uint64_t old;
  int64_t len;
  int64_t nr;
};
If you are an experienced programmer, you probably notice that the default int in c++ equals 4 bytes or, in other words, 32 bits. Therefore int64_t is twice as big, 8 bytes. This scheme applies to uint as well. If we add up all the fields of a Head block we end up with $4+4+8+8+8=32$ bytes. On the file we are reading, this chunk corresponds to:
52 45 4E 44 00 00 00 00 10 00 00 00 00 00 00 00
08 01 00 00 00 00 00 00 01 00 00 00 00 00 00 00
We notice the first four bytes happens to be readable in ASCII (because it was designed that way). It says REND and it is stored at field LargeBHead8.code. In fact, this block does not appear in the documentation since it is not meant for “normal” users. To find its meaning we need to navigate back to blender/source/blender/blenloader_core/BLO_core_bhead.hh.
/**
  * Used for #RenderInfo, basic Scene and frame range info,
  * can be easily read by other applications without writing
  * a full blend file parser.
  */
BLO_CODE_REND = BLEND_MAKE_ID('R', 'E', 'N', 'D'),
The complete translation of the 32 bits looks like this:
int code     -> 52 45 4E 44             -> REND
int SDNAnr   -> 00 00 00 00             ->    0
uint64_t old -> 10 00 00 00 00 00 00 00 ->   16
int64_t len  -> 08 01 00 00 00 00 00 00 ->  264
int64_t nr   -> 01 00 00 00 00 00 00 00 ->    1
But wait, how did we calculate the values from the hexadecimal bytes? why is an integer just a list of characters?
Okay, I did skip some important notes here. First of all, what we are seeing is just values, interpretation relies completely on the code. The first four bytes are written below next to its hexadecimal interpretation. When we read the file using a hexadecimal interpreter we are only shown the second line but the code itself is reading the bits, it has zero knowledge of what hexadecimal is or how it works.
bits 0101 0010   0100 0101   0100 1110   0100 0100
hex         52          45          4E          44
In this particular case, REND are not actually characters, it is an integer which hexadecimal representation translated to ASCII is exactly REND. If you are curious, that integer is $1145980242$.
The rest of inputs are treated exactly the same way, they are interpreted as integers.
Again, file BLO_core_bhead.hh contains what each field really means.
- code: Identifier for this #BHead. Can be any of BLO_CODE_* or an ID code like ID_OB.
- SDNAnr: Identifier of the struct type that is stored in this block.
- *old: Identifier the block had when it was written. This is used to remap memory blocks on load. Typically, this is the pointer that the memory had when it was written. This should be unique across the whole blend-file, except for
BLEND_DATAblocks, which should be unique within a same ID. - len: Number of bytes in the block
- nr: Number of structs in the array (1 for simple structs).
So, translating the bytes to natural language, we get: The code is REND, the struct type is ignored (0), it was previously written at position 16, it has length of 264 bytes and finally there is only one chunk inside it.
What do this 264 bytes contain? The first eight bytes are two integers containing the starting and ending frame of the animation. In this case we have:
01 00 00 00 ff 01 00 00
start-> 00000001 -> \(1\)end-> 000001ff -> \(1*16*16+15*16+15=511\)
The rest of 256 bytes contain the ASCII for the scene name. In fact only the first 9 bytes are used and the others are left as zeros. The conversion returns Scene.001
53 63 65 6e 65 2e 30 30 31 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
In the source code we have two files from which we can inherit this information called readfile.cc and writefile.cc.
// writefile.cc lines 1188 to 1221

struct RenderInfo {
  int sfra;                          // 4 bytes
  int efra;                          // 4 bytes
  char scene_name[MAX_ID_NAME - 2];  // 258 - 2 = 256 bytes
};                                   // = 264
...
writedata(wd, BLO_CODE_REND, sizeof(data), &data);
This code is not really used by blender as the comments in the file explain. It is mainly a legacy functionality that stayed because it can be used by third party apps. Nevertheless this is not that much useful in cases where we don’t know the scene we are aiming to render. In my .blend file I got two scenes and REND only stores the last opened one, so keep an eye on this before using the information blindly.
The next block ,TEST , is the embedded preview thumbnail of the .blend file. Unlike REND, Blender does read its contents. It uses the same 32-byte block header as REND:
54 45 53 54 00 00 00 00 e0 92 b7 4d 56 93 c5 7b
08 8a 00 00 00 00 00 00 01 00 00 00 00 00 00 00
int code     -> 54 45 53 54             -> TEST
int SDNAnr   -> 00 00 00 00             ->    0
uint64_t old -> e0 92 b7 4d 56 93 c5 7b ->  0x7BC593564DB792E0 (8918696635957482208)
int64_t len  -> 08 8a 00 00 00 00 00 00 ->  35336
int64_t nr   -> 01 00 00 00 00 00 00 00 ->    1
I want to focus on the size of this block. 35336 is quite a lot for text or certain types of information. TEST encodes the preview of the file. This means any app or browser (like windows browser, dolphin, …) can look at this chunk of bytes and extract the preview image. The first eight bytes are the dimensions 80 00 00 00 45 00 00 00 -> 128x69 pixels.
import struct
import numpy as np
import matplotlib.pyplot as plt

HEADER_SIZE = 17   # "BLENDER17-01v0501" (new large-header format)
BHEAD = struct.Struct("<4si Q q q")  # code, SDNAnr, old, len, nr = 32 bytes
"""
Part   Meaning                                         Bytes  Field
<      bytes order in little-endian, without padding   –      –
4s     4 bytes character chain                         4      code (b"TEST", b"REND"...)
i      32 bits integer                                 4      SDNAnr
Q      64 bits integer                                 8      old (puntero)
q      64 bits signed integer                          8      len
q      64 bits signed integer                          8      nr
"""

def read_thumbnail(path):
    """Return an (h, w, 4) uint8 RGBA array, or None if the file has no thumbnail."""
    with open(path, "rb") as f:
        header = f.read(HEADER_SIZE) # 17 header bytes

        # Check if .blend file is valid
        if not header.startswith(b"BLENDER"):
            raise ValueError("Not a plain .blend (maybe compressed?): %r" % header[:12])

        # We read the rest of the file
        while True:
            # read 32 bytes
            raw = f.read(BHEAD.size)

            # make sure the size is correct
            if len(raw) < BHEAD.size:
                return None

            # use python struct.unpack method
            code, sdna, old, length, nr = BHEAD.unpack(raw)

            if code == b"REND":
                # skip bytes inside REND
                f.seek(length, 1)

            elif code == b"TEST":
                # Read image
                width, height = struct.unpack("<ii", f.read(8))
                assert length - 8 == width * height * 4, "unexpected TEST size"
                pixels = np.frombuffer(f.read(width * height * 4), dtype=np.uint8)
                img = pixels.reshape(height, width, 4)
                return np.flipud(img)        # stored bottom row first

            else: # just in case. TEST always comes right after REND
                return None
I would have expected the preview image to be some kind of low resolution render of the scene but instead I got a window capture 3. This is due the conditional tree blender uses to decide how to capture the preview. At wm_files.cc:2160-2196 we see four options: USER_FILE_PREVIEW_SCREENSHOT, USER_FILE_PREVIEW_CAMERA, USER_FILE_PREVIEW_AUTO, USER_FILE_PREVIEW_NONE. Depending on you’r settings (by default is “auto”) you will get the camera preview 4 if a camera exists and a capture otherwise.
Blender Loading System
With that out of the way, it is a good moment to introduce how blender actually loads the saved files instead of the naive strategy: “read from top and separate each chunk when found”.
Blender’s strategy consists on a two step process to load a file from disk into memory.
The first step consists on:
- Find the .blend file.
- Check it has the proper header.
- Create a wrapper around it so we can read it independendtly of the operating system.
- return a FileData c++ structure.
The second step consists on:
- Parsing: read the file block by block
- Populate c++ structures with this information
- return BlendFileData c++ structure
Yea… its not that simple. In practice that is all we need to understand, we dont have to care about version managing, efficient file searching, or anything else really. But this post is about deep understanding so we will have to take a look in the deep waters of blender’s version control and parsing methodology.
When we press open file or any other method that involves a .blend document, Blender executes a method called BlendFileData *BLO_read_from_file(...) that we can find at header BLO_readfile.hh and its implementation at readblenentry.cc. Two things call our atention here:
- This method returns a
BlendFileDatastructure, more about this structure on the next section. - It has the prefix
BLO_, translated to plain english it means blender_loading library. It is a method defined in a specific library blender created to manage loading operations.
This is stright forward, you want to load a .blend file? execute this method. Thats it really. But loading the file itself is not as stright forward, the method BLO_read_from_file has many nested methods before archieving its final structure.
BlendFileData *BLO_read_from_file(...)
...
The first action of BLO_read_from_file is to makes sure the path exists. After a successful check, it executes method FileData *blo_filedata_from_file(filepath, reports). Here, reports is just an empty list where we will be appending any error or information while processing the file.
BlendFileData *BLO_read_from_file(...)
  BLI_assert(!BLI_path_is_rel(filepath));
  BLI_assert(BLI_path_is_abs_from_cwd(filepath));
  fd = blo_filedata_from_file(filepath, reports);
  ...
...
Inside blo_filedata_from_file, we call FileData *blo_filedata_from_file_open(filepath, reports), whose job is to open the file and prepare a reader for it. It calls BLI_open, which asks the operating system to open the file and returns a file descriptor: a small integer that identifies the open file in the process’s table of open files. The operating system gives the lowest free number. Numbers 0, 1 and 2 are always taken by standard input, standard output and standard error, so in a fresh program the first file gets 3. If the file can’t be opened (it doesn’t exist, or we don’t have permission), BLI_open returns -1, and a warning with the reason is added to the reports list.
BlendFileData *BLO_read_from_file(...)
  BLI_assert(!BLI_path_is_rel(filepath));
  BLI_assert(BLI_path_is_abs_from_cwd(filepath));
  fd = blo_filedata_from_file(filepath, reports);
    FileData *fd = blo_filedata_from_file_open(filepath, reports);
      const int file = BLI_open(filepath, O_BINARY | O_RDONLY, 0);
      ...
    ...
  ...
...
The way computers load and read files is out of the scope for this document but I want to clarify something.
When we say a file is “Open” it means we keep track of the starting point of this file in memory. Lets say a disk is just a bookshelf. In that case opening a file is discovering where the book is positioned in the bookshelf but we still dont know the contents of the pages. “Reading” means “load page x y and z into memory” and the system keeps track of how many pages we have read. If we try to read again, it will skip the previous pages and resume where it left.
Right now, we are only storing the position of the book and not reading anything yet.
In case you are wondering what BLI_open is, Blender has many modules and libraries reused in all parts of the source code. Some of them we have already seen like BLI_ and BLO_. This is a rough list of some libraries even though maybe I missed some of them.
| Prefix | Module | Folder |
|---|---|---|
BLI_ |
Blender library: utilities, OS wrappers | blenlib/ |
BKE_ |
Blender kernel: logic for scenes, objects, meshes… | blenkernel/ |
BLO_ |
Blender loader: reading and writing .blend files | blenloader/ |
DNA_ |
The data structures and the schema system | makesdna/ |
RNA_ |
The property system used by the UI and Python | makesrna/ |
MEM_ |
Memory allocation with leak checking | intern/guardedalloc/ |
IMB_ |
Image buffers (the thumbnail ImBuf) |
imbuf/ |
WM_ |
Window manager: windows, events, file open and save | windowmanager/ |
ED_ |
Editors and operators | editors/ |
GHOST_ |
The lowest OS layer: windows, input, GPU context | intern/ghost/ |
The method BLI_open is a wrapper around open, part of the POSIX standard that Unix-like systems (Linux, macOS, BSD) implement. When blender is being compiled, it decides against which libraries and functions it has to compile. Windows systems do not have certain operating system calls so we switch open for upone method.
fileops_c.cc

 551  #ifdef WIN32
        ...
 615    int BLI_open(...) { ... return uopen(filepath, oflag, pmode); }
        ...
 883  #else /* The UNIX world */
        ...
1199    int BLI_open(...) { ... return open(filepath, oflag, pmode); }
        ...
1572  #endif
We then execute blo_filedata_from_file_descriptor(filepath, reports, file). The purpose of this method is to wrap the reader in a generalized structure that can be reused anywhere in the code. This structure is called FileReader and provides methods to read, seek and close the file. Additionally we will use another wrapper called FileData containing references to the reports, FileReader and any other structure that may be required in the future.
BlendFileData *BLO_read_from_file(...)
  BLI_assert(!BLI_path_is_rel(filepath));
  BLI_assert(BLI_path_is_abs_from_cwd(filepath));
  fd = blo_filedata_from_file(filepath, reports);
    FileData *fd = blo_filedata_from_file_open(filepath, reports);
      const int file = BLI_open(filepath, O_BINARY | O_RDONLY, 0);
      return blo_filedata_from_file_descriptor(filepath, reports, file);
        file_reader;
        return FileData(file_reader)
      ...
    ...
  ...
...
struct FileData {
  FileReader *file = nullptr;
  BlendFileReadReport *reports = nullptr;
  DNA_ReconstructInfo *reconstruct_info = nullptr;
  ...
}
If you followed through, you probably know already that blender reads the first 7 bytes to check for the identifier “BLENDER”. If necessary, it executes decompression first. Once the file is in the correct format and has the identifier, it is converted to the FileData and then into a BlendFileData. We will explore the conversion from FileData to BlendFileData in the future sections. For now i will provide an overview to the full loading process as a tree with the most important functions:
BlendFileData *BLO_read_from_file(...)
├── FileData blo_filedata_from_file(filepath, reports)
│    ├── FileData *blo_filedata_from_file(filepath, reports)
│    │   └── FileData *blo_filedata_from_file_open(filepath, reports)
│    │       └──FileData *blo_filedata_from_file_descriptor(filepath, reports, file)
│    │          ├──FileReader *file = BLO_file_reader_uncompressed_from_descriptor(filedes)
│    │          ├──BLI_stat_t stat  = BLI_stat(filepath, &stat)
│    │          └──FileData *fd     = filedata_new(reports, file, stat)
│    └── blo_decode_and_check(fd, reports->reports)
│        └── read_file_dna
│            └── DNA_sdna_from_data
│                └── init_structDNA
├──  BlendFileData *bfd = nullptr;
├──  bfd = blo_read_file_internal(fd, filepath);
└── blo_filedata_free(fd);Dont worry about all this methods like blo_decode_and_check, blo_read_file_internal or read_file_dna and so on. They are important, don’t get me wrong, but we will explore them better in the following sections.
As a conclusion of this section
I just want you to focus on the blender strategy for designing a loading system that is splitted in two parts. They have a .blend file configured in a really particualr way divided in many chunks, all of them with a header for easy identification.
First, they created a series of methods that: find the .blend file, check it is correct, creates a wrapper around it, and finally waits for further instructions on when to read it. We can call this step FileData.
The second step is to actually ‘read the file and generate the ram memory objects’. They parse the file, get all the information while making sure it is correct and finally they fill the ram with all this structures so the program can retrieve it fast. Now we dont search an object by its bytes offsets, instead we call the pointers to the structures in ram memory (way faster 👍). We call this the BlendFileData.
Blender Parsing
Lets go back to the wrapper function BLO_read_from_file that we saw in the previous section. This is how it looks in the blender repo:
BlendFileData *BLO_read_from_file(const char *filepath,
                                  eBLOReadSkip skip_flags,
                                  BlendFileReadReport *reports)
{
  BLI_assert(!BLI_path_is_rel(filepath));
  BLI_assert(BLI_path_is_abs_from_cwd(filepath));

  BlendFileData *bfd = nullptr;
  FileData *fd;

  fd = blo_filedata_from_file(filepath, reports);
  if (fd) {
    fd->skip_flags = skip_flags;
    bfd = blo_read_file_internal(fd, filepath); // <----
    blo_filedata_free(fd);
  }

  return bfd;
}
Inside the if statement we find blo_read_file_internal(fd, filepath) which recieves the already generated FileData structure and turns it into a BlenderFileData structure.
There is one issue though. Blender’s source code changes. They get new structures, new functionalities and remodel already existing systems. This represents a big issue on softwares that develop really fast with big changes almost every month. Blender named this solution Structure DNA.
We can summarize it as: The .blend file will contain a block called DNA1 at the end of the file which will store the size and fields of each structure a blender file is designed to contain.
Lets say Blender 4.0 saves materials with this struct:
struct Material {        // 4.0
  ID id;
  float r, g, b;
  short flag;
};
In version 4.1, a developer adds a field and makes “flag” larger:
struct Material {        // 4.1
  ID id;
  float r, g, b;
  float roughness;       // new
  int flag;              // was short
};
When we open the old .blend file into the new version, we first read this DNA1 block. Inside the block we find that Material structure is stored as Material = id, r, g, b, flag (short) while the compiled schema inside blender’s installation says id, r, g, b, roughness, flag (int). There is a discrepancy between versions that prevents to load the old fields using a newer blender file parser. While reading the DNA1 structure, blender stores flags alerting of this incompatibility with compflags[Material] = SDNA_CMP_NOT_EQUAL.
The method in charge of all this “cheking” compatibility is in fact blo_read_file_internal(...) which takes 454 lines, and that is without counting the functions it calls from inside. You are more than welcome to look at it at source/blender/blenloader/intern/readfile.cc. In this post we are simply summarizing it.
blo_read_file_internal                  readfile.cc:4446
└─ read_libblock                        readfile.cc:4620 (call)
   ├─ read_id_struct                    readfile.cc:3683 (reads the ID struct itself)
   │  └─ read_struct                    readfile.cc:2015
   │     └─ DNA_struct_reconstruct      readfile.cc:1952
   └─ read_data_into_datamap            readfile.cc:3748 (reads the BLO_CODE_DATA blocks after the ID)
      └─ read_struct                    readfile.cc:2986
         └─ DNA_struct_reconstruct      readfile.cc:1952
For every Material block in the .blend file, DNA_struct_reconstruct allocates a new zeroed 4.1 struct and fills it using the stored values if they exist.
   4.0 block (file)                                 4.1 block (memory)
                                                    zeroed    final
┌───────────┬───────┐                      ┌───────────┬────────┬───────┐
│ id        │ "Mat" │ ───── memcpy ──────> │ id        │   0    │ "Mat" │
├───────────┼───────┤                      ├───────────┼────────┼───────┤
│ r         │  0.8  │ ───── memcpy ──────> │ r         │   0    │  0.8  │
├───────────┼───────┤                      ├───────────┼────────┼───────┤
│ g         │  0.2  │ ───── memcpy ──────> │ g         │   0    │  0.2  │
├───────────┼───────┤                      ├───────────┼────────┼───────┤
│ b         │  0.1  │ ───── memcpy ──────> │ b         │   0    │  0.1  │
├───────────┼───────┤                      ├───────────┼────────┼───────┤
│ (absent)  │   -   │    no match in 4.0   │ roughness │   0    │   0   │ <- never written
├───────────┼───────┤                      ├───────────┼────────┼───────┤
│ flag      │   3   │ ─ cast short→int ──> │ flag      │   0    │   3   │
│ (short)   │       │                      │ (int)     │        │       │
└───────────┴───────┘                      └───────────┴────────┴───────┘
In the above diagram, id, r, g, b are found by name and copied (RECONSTRUCT_STEP_MEMCPY).
On the other hand, field flag has the same name but a different type, so it’s converted from short to int (RECONSTRUCT_STEP_CAST_PRIMITIVE).
On the third case, roughness isn’t in the old file, so it stays 0 (RECONSTRUCT_STEP_INIT_ZERO).
When a change is introduced in the code and we are aware that in the future there may be old files that need to be updated, they will need to populate non existen fields with a default value. That is what versioning is for. Versioning is a step on the file loading process that aims to check default values for fields that did not exist before. In the third step we simply populated roughness with value 0 which in most cases is not desired. A more standard approach is to asign value 0.5 so it is neither reflective or diffuse.
To define a default value we need to modify the source code itself.
if (!MAIN_VERSION_FILE_ATLEAST(bmain, 401, 3)) {
  for (Material *ma : bmain->materials) ma->roughness = 0.5f;
}
This is just an example. The code above shows that if the .blend file was stored with a smaller version than 4.1.3, it will need in fact to update the already stored structures to match the new material structure. I invite you to check any of the following files to see for yourself how blender manages versioning:
- versioning_250.cc
- versioning_260.cc
- versioning_270.cc
- versioning_280.cc
- versioning_290.cc
- versioning_300.cc
- versioning_400.cc
- versioning_401.cc
- versioning_402.cc
- versioning_502.cc
For forward compatibility (opening a modern file 4.1 in older blender versions 4.0) we make the same checks. roughness has no field to go into, so it’s dropped. flag is converted from int to short. The file loads, but the roughness value is lost if you re-save it in version 4.0.
Renaming is a separate case, and it doesn’t involve reconstruction. If r were renamed to color_r in the source, dna_rename_defs.h would get an entry: DNA_STRUCT_RENAME_MEMBER(Material, r, color_r). There are about 260 of these member renames. At build time, makesdna uses the table to write the old name into the DNA, so files keep saying r, both old and new. C++ code uses color_r, while the name stored on disk never changes, so old files still match.
Dont worry if all this feels too overwhelming .The idea is to be aware of the existence of multiple mechanisms inside the code that manage the loading and understanding of a blend file. The more time we spend reading and analyzing code and its designing choices the more we assimilate it.
On our example file we can, in fact, find the DNA1 struct by searching the string in the ASCII representation:
0007a2f0: 00 00 00 00 00 00 44 4e 41 31 00 00 00 00 d0 f4  ......DNA1......
0007a300: 21 a6 20 b7 a5 7e d8 0d 02 00 00 00 00 00 01 00  !. ..~..........
0007a310: 00 00 00 00 00 00 53 44 4e 41 4e 41 4d 45 99 14  ......SDNANAME..
0007a320: 00 00 2a 64 65 73 63 72 69 70 74 69 6f 6e 00 72  ..*description.r
0007a330: 6e 61 5f 73 75 62 74 79 70 65 00 5f 70 61 64 5b  na_subtype._pad[
0007a340: 34 5d 00 2a 69 64 65 6e 74 69 66 69 65 72 00 2a  4].*identifier.*
0007a350: 6e 61 6d 65 00 76 61 6c 75 65 00 69 63 6f 6e 00  name.value.icon.
And again we can take the first 32 bytes containing the header:
44 4e 41 31 00 00 00 00 d0 f4 21 a6 20 b7 a5 7e
d8 0d 02 00 00 00 00 00 01 00 00 00 00 00 00 00

int      code   -> 44 4e 41 31             -> DNA1
int      SDNAnr -> 00 00 00 00             -> 0
uint64_t old    -> d0 f4 21 a6 20 b7 a5 7e -> 0x7EA5B720A621F4D0
int64_t  len    -> d8 0d 02 00 00 00 00 00 -> 134616
int64_t  nr     -> 01 00 00 00 00 00 00 00 -> 1
We can see it is a really big chunk of information. It will take a while to digest but lets try our best. The important concept here is that DNA1 is a wrapper of an independent structure called SDNA also found in the file itself as 53 44 4e 41 -> SDNA. In the example below, look at the last line and you will see SDNANAME. They are two independent strings (SDNA, NAME)but because we are reading directly from the binary file they just apear one next to the other:
0007a2f0: 00 00 00 00 00 00 44 4e 41 31 00 00 00 00 d0 f4  ......DNA1......
0007a300: 21 a6 20 b7 a5 7e d8 0d 02 00 00 00 00 00 01 00  !. ..~..........
0007a310: 00 00 00 00 00 00 53 44 4e 41 4e 41 4d 45 99 14  ......SDNANAME..
At dna_genfile.cc:368-557 we see the parser init_structDNA(...). Its purpose is to skip all the file until reaching SDNA structure. Once it is loaded, it starts parsing it. It is divided in four sections called:
- NAME: list of names
- TYPE: list of types
- TLEN: size of the types
- STRC: list of structures
In the pasted chunk of binary content we can only see NAME but I swear the rest are there too, just a little bit after.
With those four segments, we can recover the structures on which the file was stored. Lets see this with two structures called IDPropertyData and IDPropertyUIDataEnumItem:
struct IDPropertyUIData {
  char *description;
  int rna_subtype;
  char _pad[4];
};

struct IDPropertyUIDataEnumItem {
  char *identifier;
  char *name;
  char *description;
  int value;
  int icon;
};
Look how the section starts with code NAME. We are provided the number of names in this segment but not the total lengh since that is arbitrary. To know when a name starts or ends we check the suffix “x00” and we keep track of how many names we have already collected:
4e 41 4d 45 -> NAME
99 14 00 00 -> 5273 (number of NAMES)
2a 64 65 73 63 72 69 70 74 69 6f 6e 00   ->  "*description."   name #0
72 6e 61 5f 73 75 62 74 79 70 65 00      ->  "rna_subtype."    name #1
5f 70 61 64 5b 34 5d 00                  ->  "_pad[4]."        name #2
2a 69 64 65 6e 74 69 66 69 65 72 00      ->  "*identifier."    name #3
2a 6e 61 6d 65 00                        ->  "*name."           name #4
76 61 6c 75 65 00                        ->  "value."          name #5
69 63 6f 6e 00                           ->  "icon."           name #6
...
73 65 6c 69 74 65 6d 00 00 00            ->  "selitem..."      name #5272
Now we reach all the types the .blend file contains. This will be reused by the structures as well as creating an entry for each structure itself.
54 59 50 45 -> TYPE
71 04 00 00 -> 1137 (number of TYPEs)
63 68 61 72 00                              ->  "char."       type #0
75 63 68 61 72 00                           ->  "uchar."      type #1
73 68 6f 72 74 00                           ->  "short."      type #2
75 73 68 6f 72 74 00                        ->  "ushort."     type #3
69 6e 74 00                                 ->  "int."        type #4
6c 6f 6e 67 00                              ->  "long."       type #5
75 6c 6f 6e 67 00                           ->  "ulong."      type #6
66 6c 6f 61 74 00                           ->  "float."      type #7
64 6f 75 62 6c 65 00                        ->  "double."     type #8
69 6e 74 36 34 5f 74 00                     ->  "int64_t."    type #9
75 69 6e 74 36 34 5f 74 00                  ->  "uint64_t."   type #10
76 6f 69 64 00                              ->  "void."       type #11
69 6e 74 38 5f 74 00                        ->  "int8_t."     type #12
72 61 77 5f 64 61 74 61 00                  ->  "raw_data."   type #13
49 44 50 72 6f 70 65 72 74 79 55 49 44 61
74 61 00                                    ->  "IDPropertyUIData."          type #14
49 44 50 72 6f 70 65 72 74 79 55 49 44 61
74 61 45 6e 75 6d 49 74 65 6d 00            ->  "IDPropertyUIDataEnumItem."  type #15
...
58 72 41 63 74 69 6f 6e 4d 61 70 00 00 00 00 -> "XrActionMap..."             type #1136
We are now provided the number of bytes each type has:
54 4c 45 4e -> TLEN
01 00 -> 1      sizeof(char)
01 00 -> 1      sizeof(uchar)
02 00 -> 2      sizeof(short)
02 00 -> 2      sizeof(ushort)
04 00 -> 4      sizeof(int)
04 00 -> 4      sizeof(long)
04 00 -> 4      sizeof(ulong)
04 00 -> 4      sizeof(float)
08 00 -> 8      sizeof(double)
08 00 -> 8      sizeof(int64_t)
08 00 -> 8      sizeof(uint64_t)
00 00 -> 0      sizeof(void)
01 00 -> 1      sizeof(int8_t)
00 00 -> 0      sizeof(raw_data)
10 00 -> 16     sizeof(IDPropertyUIData)           <- our first struct
20 00 -> 32     sizeof(IDPropertyUIDataEnumItem)   <- our second struct
...
68 00 -> 104    sizeof(XrActionMap)                   type #1136
00 00 -> (padding, 1137 shorts = 2274 bytes -> align to 4)
STRC connects names to structs by index. Each STRC entry says “struct X has N members, and they are these (type index, name index) pairs”. We know when each starts or ends by reading the chunk in order. The first two bytes are the type index and the next two are the number of fields. With that information we can compute the length as type_index -> 2 bytes + member count -> 2 bytes + member count × 4 bytes.
53 54 52 43 -> STRC
e1 03 00 00 -> 993 (number of STRCs)

0d 00       -> type #13 "raw_data"              struct #0
00 00       -> 0 fields

0e 00       -> type #14 "IDPropertyUIData"      struct #1
03 00       -> 3 fields
00 00 00 00 -> type #0 "char" / name #0 "*description"  ->  char *description;
04 00 01 00 -> type #4 "int"  / name #1 "rna_subtype"   ->  int rna_subtype;
00 00 02 00 -> type #0 "char" / name #2 "_pad[4]"       ->  char _pad[4];

0f 00       -> type #15 "IDPropertyUIDataEnumItem"      struct #2
05 00       -> 5 fields
00 00 03 00 -> type #0 "char" / name #3 "*identifier"   ->  char *identifier;
00 00 04 00 -> type #0 "char" / name #4 "*name"         ->  char *name;
00 00 00 00 -> type #0 "char" / name #0 "*description"  ->  char *description;
04 00 05 00 -> type #4 "int"  / name #5 "value"         ->  int value;
04 00 06 00 -> type #4 "int"  / name #6 "icon"          ->  int icon;
...
We now have all the information required to understand how the file was previously stored and we have the tools to upadte this information to work on newer or older versions.
NAME:  list of names       ("*description", "rna_subtype", ...)
TYPE:  list of type names  ("char", "int", ..., "IDPropertyUIData", ...)
TLEN:  size of each type   (1, 4, ..., 16, ...)
STRC:  for each struct:  [type index][member count][type, name][type, name]...
It is time to make a technical stop!!!
This has been a heck of a journy and it starts to feel foggy and confusing. I definetly need to abstract many things away and that is why the previous sections were dense. I will now proceed on summarizing in plain text what just happend and why, instead I will introduce some of blender’s code.
First of all, the above explanation had the intetion of explaining how blender parses a file. It starts by makeing some general tests like the format and then it loads the stored SDNA. Once loaded it is compared to Blender’s compiled SDNA to make sure they match.
Lets call them host_SDNA (as blenders compiled SDNA) and remote_SDNA (as an arbitrary SDNA of any procedence).
On starting the program we store host_SDNA into memory. We do this through a method called DNA_sdna_current_get() that, at any place in the code, allows us to retrieve host_SDNA.
At readfile.cc:1162, we store a pointer to host_SDNA calling DNA_sdna_current_get(). We then load the remote_SDNA by calling read_file_dna → DNA_sdna_from_data → init_structDNA.
The two are compared to create the apropaite flags:
- Look up the same name in Blender’s schema. Not found → SDNA_CMP_REMOVED.
- Different number of members → NOT_EQUAL.
- Different total size (TLEN) → NOT_EQUAL.
- Compare the members one by one, in order: different type name → NOT_EQUAL; different member name → NOT_EQUAL; a pointer while the pointer sizes differ → NOT_EQUAL.
- If a member is itself a struct (like ID id), compare that struct first. If it isn’t equal, the parent isn’t either.
- Otherwise → SDNA_CMP_EQUAL.
The comparison is strict and positional: it checks each slot against the same slot in the other struct. If a field only moves, the struct still contains the same fields, but it’s marked NOT_EQUAL because its bytes are no longer in the same place and a plain copy would put values in the wrong fields. Matching by name only happens later, when the conversion steps are built, and that’s what lets each moved field keep its value.
DNA_reconstruct_info_create then precomputes the conversion steps (MEMCPY, CAST_PRIMITIVE, INIT_ZERO, …) for every struct marked NOT_EQUAL. Both results are stored in FileData.
The versioning hapens after this. It checks the prevoius version the file was stored from and the current version. The code exposes the value it has to use for populating new values.
Thats it, this is blender parsing strategy. Of course the code has a bit more complexity, additional checks, pointers, structures and some other additional design choices. I want to prioritize a mental model of the code so when reading the actual source it becames clear what each part is doing instead of explaining one by one each function from the start.
As a gift I will be showing now all the blocks that exist in the .blend file and some of the sublocks we have seen so far.
.blend
  ├── BLENDER header
  ├── REND
  │   ├── start/end frame
  │   └── scene name
  ├── TEST
  │   ├── width/height
  │   └── pixels
  ├── GLOB
  │   ├── subversion / minversion
  │   ├── current screen / scene / view layer
  │   ├── file flags / global flags
  │   ├── build timestamp / build hash
  │   ├── filepath
  │   └── color space name + matrix
  ├── ID blocks
  │   │
  │   │   Interface
  │   ├── WM  window manager
  │   ├── WS  workspace
  │   ├── SR  screen
  │   │
  │   │   Scene structure
  │   ├── SC  scene
  │   ├── GR  collection
  │   ├── OB  object
  │   ├── WO  world
  │   │
  │   │   Object data
  │   ├── ME  mesh
  │   ├── CV  curves (hair)
  │   ├── CU  curve, legacy
  │   ├── MB  metaball
  │   ├── PT  point cloud
  │   ├── VO  volume
  │   ├── GP  grease pencil
  │   ├── GD  grease pencil, legacy
  │   ├── LT  lattice
  │   ├── AR  armature
  │   ├── CA  camera
  │   ├── LA  light
  │   ├── LP  light probe
  │   ├── SK  speaker
  │   ├── KE  shape keys
  │   │
  │   │   Shading and textures
  │   ├── MA  material
  │   ├── NT  node tree
  │   ├── TE  texture
  │   ├── IM  image
  │   ├── LS  Freestyle line style
  │   │
  │   │   Animation and simulation
  │   ├── AC  action
  │   ├── PA  particle settings
  │   ├── CF  cache file
  │   │
  │   │   Painting and sculpting
  │   ├── BR  brush
  │   ├── PL  palette
  │   ├── PC  paint curve
  │   │
  │   │   Media and other
  │   ├── MC  movie clip
  │   ├── MS  mask
  │   ├── SO  sound
  │   ├── VF  font
  │   └── TX  text
  ├── LI  (library) + linked placeholders
  ├── USER
  ├── DNA1
  │   ├── SDNA
  │   ├── NAME
  │   ├── TYPE
  │   ├── TLEN
  │   └── STRC
  └── ENDB
In the future we will study this components by themselves now that we understand where they live and how they are writend/readed. Not only that but we will also study the ID blocks parsing methodology and what the rest of blocks really mean.
And in case you are still unsure of understanding everything that happened in this sections, here is a summary:
- User starts blender.
- User decides to load a .blend file.
- Blender executes method BLO_read_from_file.
- BLO_read_from_file reads the SDNA block from inside .blend.
- All blocks from the SDNA are checked against blenders internal SDNA.
- All missalignments between both SDNA are corrected in a list of “what should we do once we load the real data”.
- The migration is applied to the .blend data.
- We return the BlendFileData containing all structures.
and this is the final streucture that contains everithing blender owns:
blender/source/blender/blenloader/BLO_readfile.hh

struct BlendFileData : NonCopyable, NonMovable {
  Main *main = nullptr;
  UserDef *user = nullptr;

  int fileflags = 0;
  int globalf = 0;
  /**
   * Typically the actual filepath of the read blend-file, except when recovering
   * save-on-exit/autosave files. In the latter case, it will be the path of the file that
   * generated the auto-saved one being recovered.
   *
   * NOTE: Currently expected to be the same path as #BlendFileData.filepath.
   */
  char filepath[/*FILE_MAX*/ 1024] = {};

  /** TODO: think this isn't needed anymore? */
  bScreen *curscreen = nullptr;
  Scene *curscene = nullptr;
  /** Layer to activate in workspaces when reading without UI. */
  ViewLayer *cur_view_layer = nullptr;

  eBlenFileType type = eBlenFileType(0);
};
main (Main *): Main is Blender’s database. It holds one list per data type (scenes, objects, meshes, materials, images, node trees, …), and every ID block from the file ends up in one of those lists. Almost everything you think of as “the file” is here.
user (UserDef *): These are the theme, keymaps, add-ons and so on. It’s only filled when the file has a USER block, which normally means the startup file or the preferences file. A regular .blend has none, so this is usually empty.
filepath (text, 1024 characters): where the file is. Normally the path you opened. When recovering an autosave, it’s the path of the original file instead, so saving goes back to the right place. This is the same value as relabase in FileData.
Structures inside Blender
Well, now we understand how blender stores and retrieves the information from disk. But … what information can be stored?
Anyone that has used blender has used at least an “object” and a “mesh” structure. It is basically mandatory. Lets put for example the default cube. This cube lives.
Audaspace
Blender Data Structures
Once we have finished editing a file, it has to be stored somehow the same way it must be loaded in memory at execution time. Blender implements a read/write library that stores Data Structures and loads them back when necessary.
This building blocks are the essence of blender. They compose the building blocks of the software and we can think of them as lego pieces. Blender has developed the $2\times2$ red piece with two toppings and the $1\times1$ green piece. I, myself would like to build a bridge with this blocks so I make as many instances as I wish and build the wall. At saving the file, we just end up with a .blend file that contains a list of this objects, they’re position rotation and scale as well as any other property they may have.
It is a silly example but if I do it correctly, it will help generate intuition for less experienced users on code architecture.
Lets now deep down into a more specific example!!
A Data Structure that everyone has used without noticing is the Mesh Data Structure mesh data documentation
In this scene of blender we see three different objects, each of them has a unique mesh data associated to them. Look what happens when we use the same mesh for all the objects.
Suddenly we have the same geometry on all objects but with an additional transformation added to each one. Do you know what that is? It is called instance and is huge. Instances are the funding block of all game engines and 3D applications. But then, if the object instance is independent of the mesh instance, what is object? It is just another building block called Object Data altogether with Object.
This graph is an over simplification. In blender, each of this data structures have hundreds of attributes and they additionally rely on arrays and tensors that contain even more information (like vertices, edges and faces connections).
A better visualization of this structures shown inside blender itself. Visit Editor and Outliner for the documentation on what are editors inside blender and what is the Outliner editor specifically. We cite the page directly:
Blender provides a number of different editors for displaying and modifying different aspects of data. An Editor is contained inside an Area which determines its size and placement within the Blender window. Every area may contain any type of editor.
The Editor Type selector, the first button at the left side of a header, allows you to change the Editor in that area. It is also possible to open the same Editor type in different areas at the same time.